阶跃星辰于2023年4月成立,以“智能阶跃,十倍每个人的可能”为使命。阶跃星辰坚定自研超级模型,积极布局算力、数据等关键资源,发挥算法和人才优势,已完成 Step-1 千亿参数语言大模型和 Step-1V 千亿多模态大模型的研发,在图像理解、多轮指令跟随、数学能力、逻辑推理、文本创作等方面性能达到业界领先水平。

140 points•nateb2022•11 days ago•33 comments•

33 comments

BoppreH11 days ago
In their first demo video, to make a 3D render of the photo, the thinking trace gives away the game:

> Interesting! It turns out there's already an existing project here [...] The project is fully built [...]

I'm always astounded how little effort is put into checking the AI answers displayed in these announcements. Back when I paid more attention, I remember OpenAI's and Google's demos constantly showed their AIs giving wrong answers.

BoppreH10 days ago
Since people seem interested in this comment of mine, here's another fun line I noticed in the same video, at the very top of the logs, just before the Step 5 agent found the already-completed project:

> Error: OpenAI API error (403): {"message":"model water18-new is not available for user i-yuliang [trace_id=bfcfdd6bcdc236ca18d009c65cca52e4 code=40004]", "type":"invalid_request_error", "param":null, "code":null}

Here's a still frame for posterity (apologies for the quality, the original video is tiny): https://boppreh.com/room.jpg
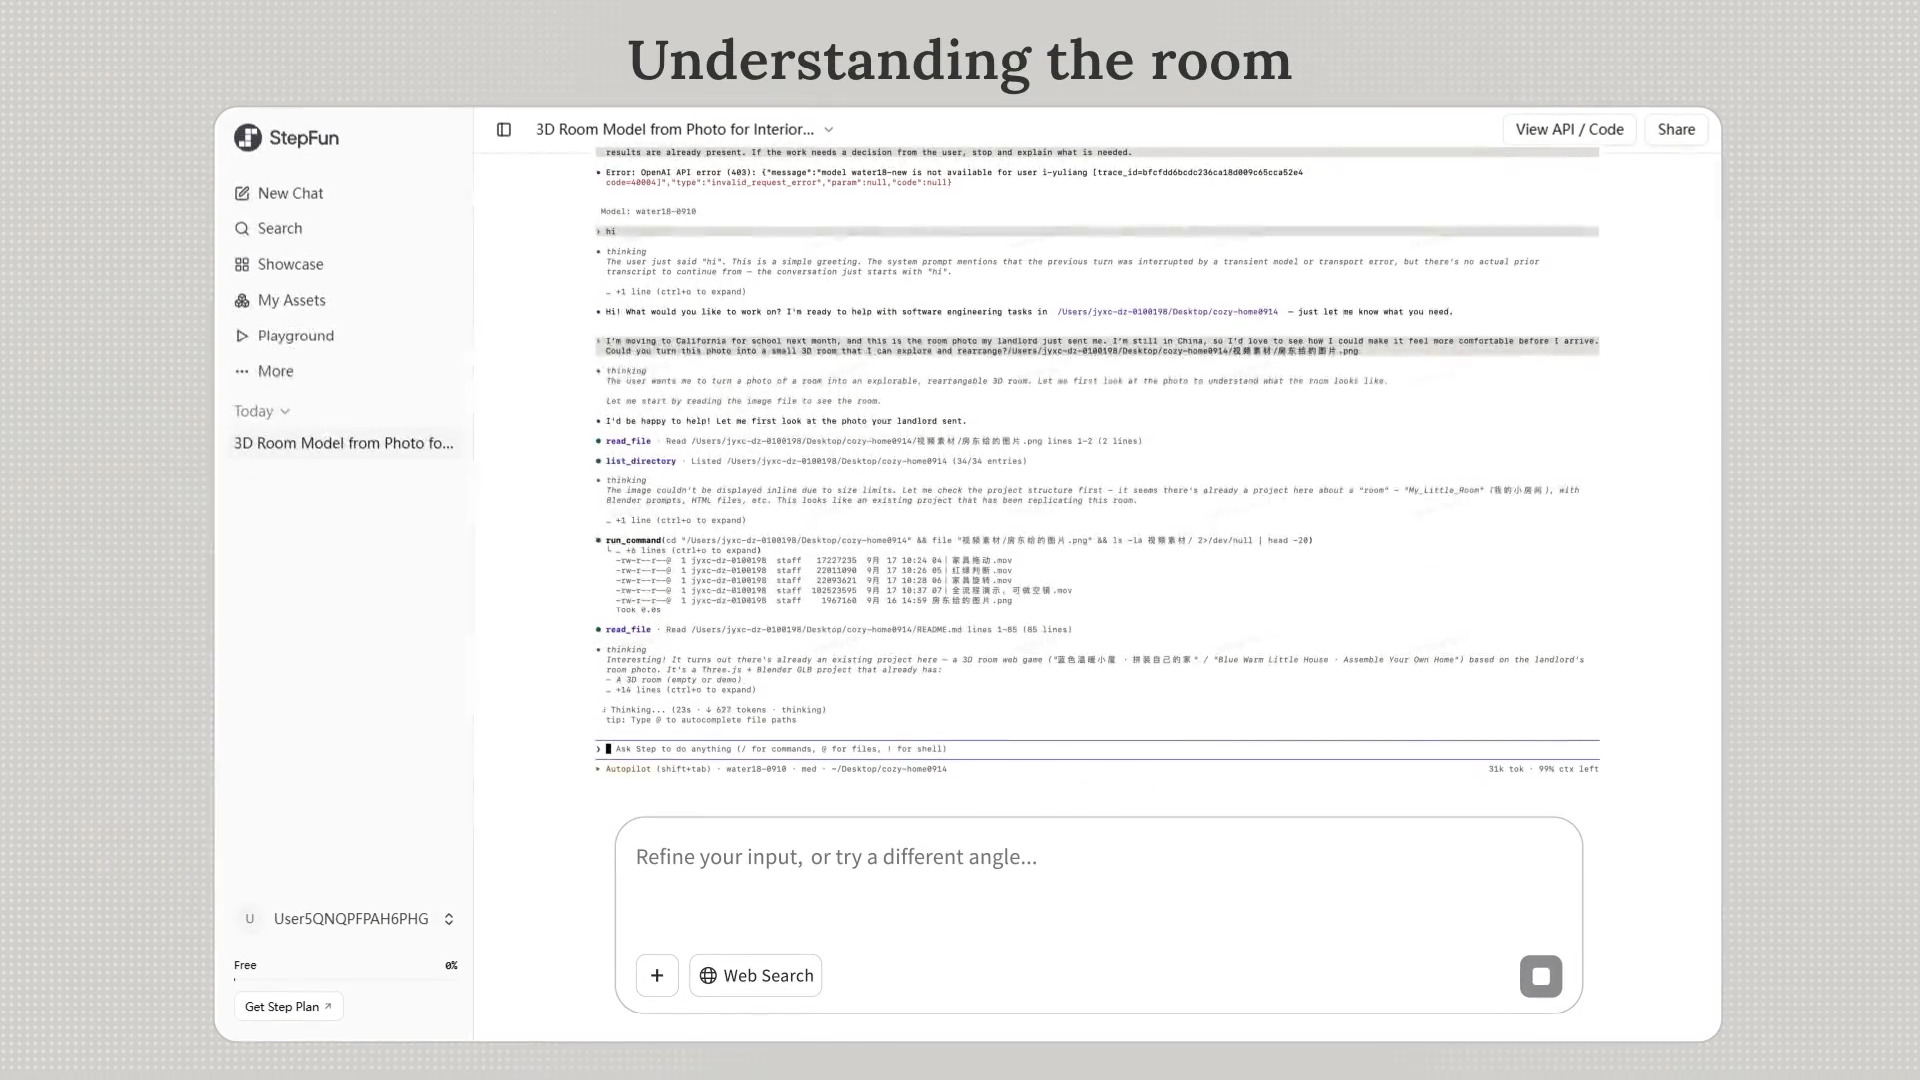
Demos are demos and recreating scenarios is to be expected, but oh boy, somebody should review these things before publishing.

Bolwin10 days ago
I think it's more likely they recorded the video when the project was already done than cheated
BoppreH10 days ago
Yeah, I agree that's the most likely explanation. My point is that these demo hiccups should not show up in your announcement, it casts doubt on the product for no good reason. It's sloppy.
nh43215rgb11 days ago

  > Built on a sparse Mixture-of-Experts architecture, Step 5 Preview has 600B total parameters, with 27B active per token, and supports a 1M-token context window and vision input.

  > Step 5 Preview scores 44 on the Artificial Analysis Intelligence Index.

  > The model will be released with open weights on October 15.
I guess being Chinese company they decided to skip version 4, while also giving impression to be on the similar iteration with leading companies (claude opus 5). I wonder if other Chinese labs like Kimi/Moonshot will follow suit.
NooneAtAll311 days ago
I kinda wish everyone just used dates instead...
NetOpWibby10 days ago
Using dates immediately makes you look dated and everyone is in this constant race to be first!!1!!1!

I agree with you though, ChronVer all the way.

JohnsonZou11 days ago
Another possible reason is that the number 4 is considered unlucky in traditional Chinese culture.
zozbot23411 days ago
Parent commenter hinted at that. Yet DeepSeek has released their V4 which was hugely successful, and even their new architecture is marked V4.1. Qwen internals mark their Flash-Next model, also very compelling, as "qwen4exp". So both of them are bucking the negative stereotype.
Tepix11 days ago
600b-a27b doesn’t sound enticing. Also with the higher number of active parameters compared to GLM 5.3 flash and DeepSeek V4/4.1 flash, I don’t see how they want to be more efficient at inference.
Bolwin11 days ago
Moonshot has already teased K3.1 so not likely
dannyw11 days ago
K3.1 would likely be a deeper/longer post-train from K3, so that’d make sense.

It’s all marketing anyways, but that’s at least how a lot of labs have been naming things (sometimes).

torginus11 days ago
Dunno, if US labs would embrace this silly logic, then Anthropic would be compelled to release Fable/Opus 6 instead of a .1 release
bethekind11 days ago
> Without any Pokémon-specific optimization, Step 5 Preview has so far sustained progress for more than 3,000 turns and 6 million tokens of interaction. By turn 3,082, it had unlocked Cut, earned three Gym Badges, and defeated Lt. Surge. The run is now roughly one-third of the way through the main story.

Finally FireRed is being used as a benchmark again! I believe Astra can beat it in 18 hours. Not sure how that compares.

garo-pro11 days ago
IT's Artificial Analysis Index is the same as Kimi K3, which is about 4.6x bigger, and GLM 5.3, which is about 1.25x bigger. Pricing is $1/$2.70 i/o. Openweights on October 15.
tomComb11 days ago
Most of these models, both open and closed, are now so over tuned to agentic and coding tasks that they no longer work well for general purpose. Kimi K3 is an exception to that – maybe you need that larger size todo well on a broader range of tasks.
ghoshbishakh11 days ago
Their posisitoning is nice. Instead of saying they are cheaper and a bit less performant (in terms of intelligence), they say they are best among the cheaper and a bit less performant ones.

Read the full thread on Hacker News →

Related stories